The problem
Personalisation at scale usually means a merge field wearing a costume. “I saw you’re the {{title}} at {{company}}” is not personalisation, and everyone who receives it knows.
Real personalisation needs research, and research is expensive. Which means the interesting question is not how to write the email. It is which accounts deserve the research spend at all.
The system
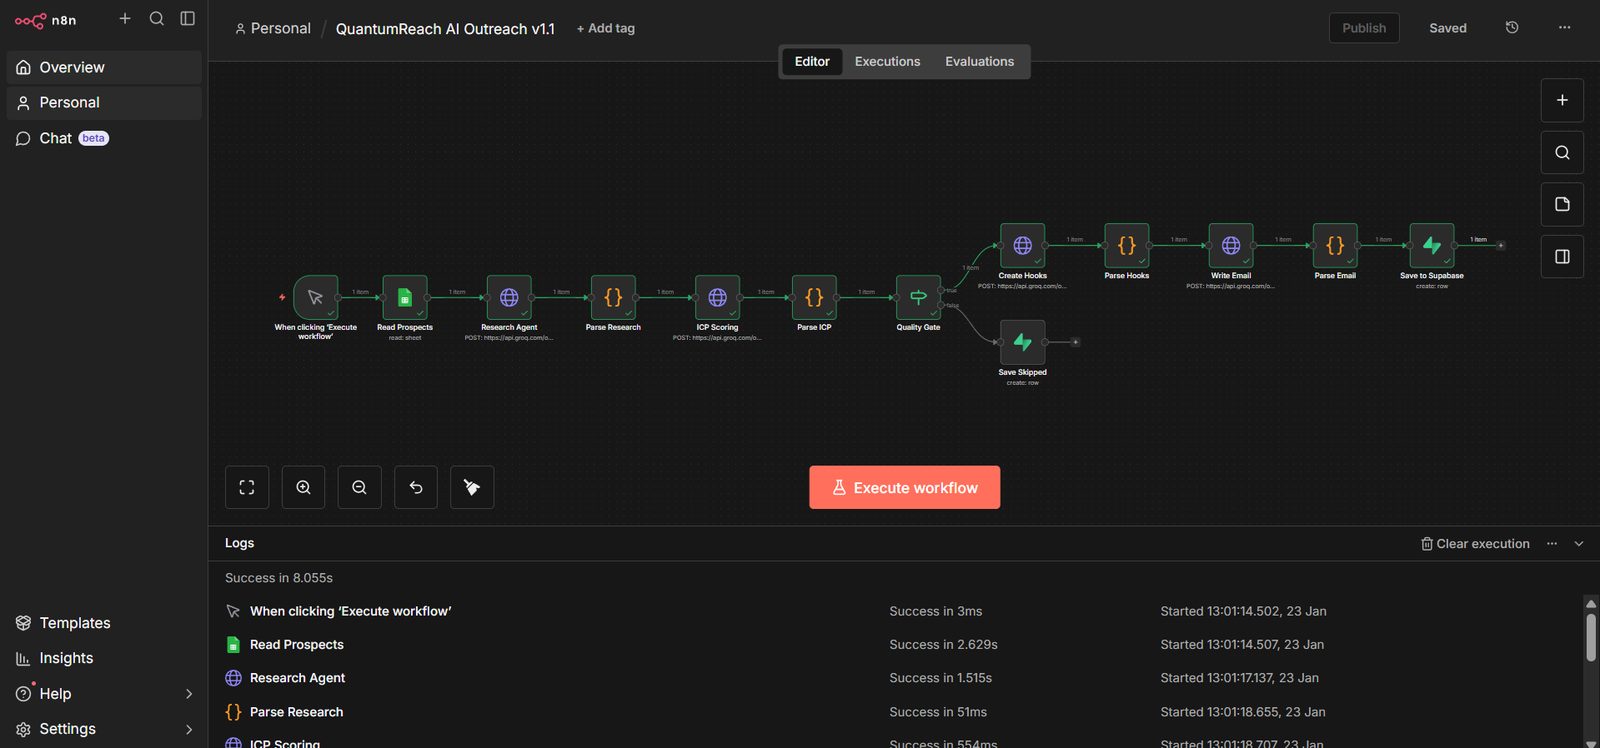
Read prospects from a sheet. Run a research agent against each account. Parse the research into structured fields. Score ICP fit. Then a quality gate. Only what clears the gate reaches personalisation and a drafted email.
State in Supabase, source list in Google Sheets, orchestration in n8n.
The decision
The gate goes before the writing, not after
The obvious order is: research everything, write everything, then filter the output. That way you can see what you are throwing away.
It is also the order that pays for every draft you discard. Generation is the expensive step and the slow one, so the filter belongs in front of it.
This is the same argument as the enrichment waterfall in the outbound agent and the confidence floor in the reply classifier: put the cheap decision before the expensive one, and let the system fail early.
It drafts. It does not send.
Same boundary as everything else I build. The email is written and left for a person.